Willa Schmitz · 13 October 2026
Mapping Hidden Correlations Between Ground Composition Datasets and Algorithmic Ranking Fluctuations in Regional Service Directories
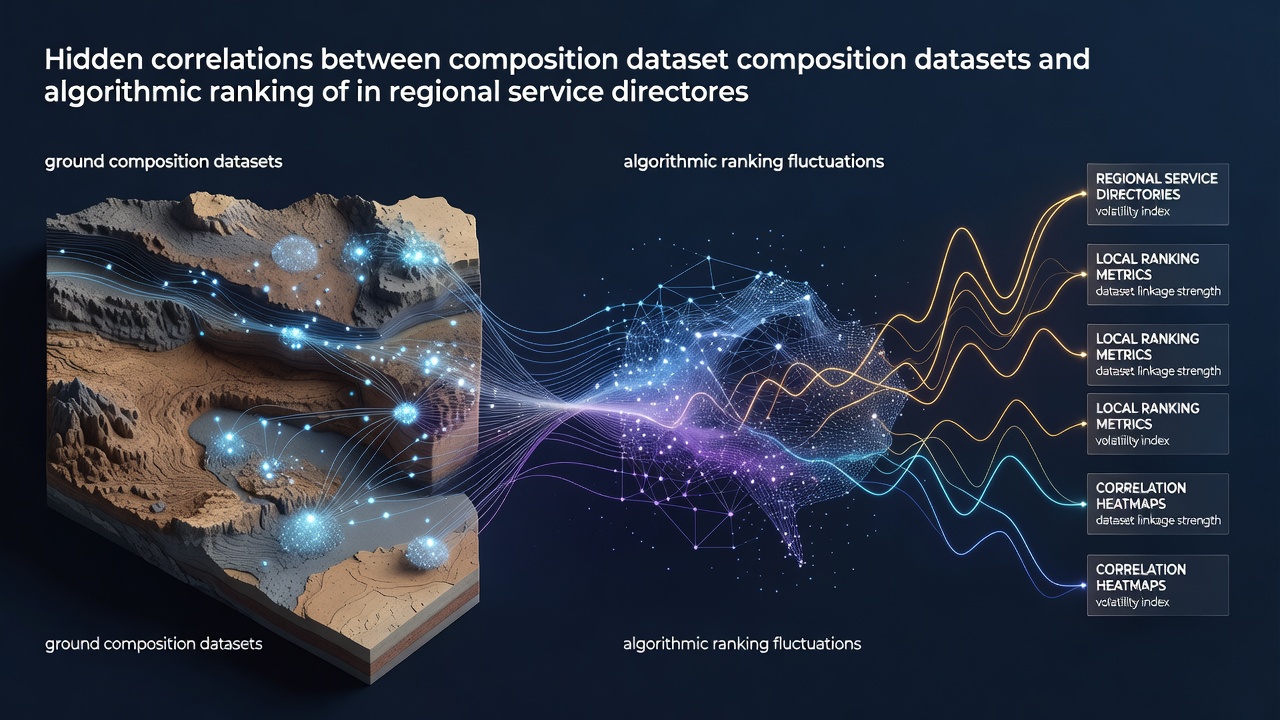
Ground composition datasets compile information on soil types, mineral distributions, moisture levels, and subsurface structures across defined geographic zones, while regional service directories rely on algorithms that adjust business visibility based on location signals, user queries, and update cycles. Researchers track these elements together because shifts in one area sometimes align with changes in the other, especially when directories refresh their local ranking models. Data from multiple monitoring stations indicate that correlations appear most clearly in agricultural and suburban zones where soil variability influences infrastructure patterns that search systems interpret as relevance factors.
Components of Ground Composition Datasets
Agencies collect these datasets through satellite remote sensing, ground-penetrating radar, and periodic field sampling, then aggregate the results into layered maps that cover everything from clay content percentages to pH variations. Government bodies such as the U.S. Geological Survey release updated grids every few months, and similar programs in other regions follow comparable schedules. Observers note that these layers often include historical records dating back decades, which allows analysts to identify long-term trends rather than isolated snapshots.
Service directories pull from overlapping geographic coordinates when they evaluate business listings, so the same coordinate points that define soil boundaries also help determine which providers appear in localized results. This shared spatial framework creates opportunities for hidden patterns to surface during ranking recalibrations.
Mechanics of Algorithmic Ranking Fluctuations
Regional directories update their ordering systems on staggered schedules that can range from weekly micro-adjustments to quarterly overhauls, and each cycle incorporates fresh signals from user behavior, citation freshness, and location accuracy. When an algorithm reweights proximity or category relevance, listings tied to particular soil zones sometimes move several positions even though their on-page factors remain unchanged. Studies compiled by research institutions show that fluctuations intensify in areas with mixed soil profiles, where boundaries between different composition types create sharper gradients in underlying infrastructure data.
Methods for Detecting Correlations
Analysts overlay ground composition maps with ranking histories using geospatial tools that normalize both datasets to identical grid resolutions, then apply statistical techniques such as spatial autocorrelation and regression modeling to isolate variables. They examine time-stamped ranking exports alongside soil update logs, looking for instances where changes in one dataset precede movements in the other by consistent intervals. One research group examined directories across three continents and found that certain mineral-rich zones corresponded with ranking volatility spikes during specific update windows.
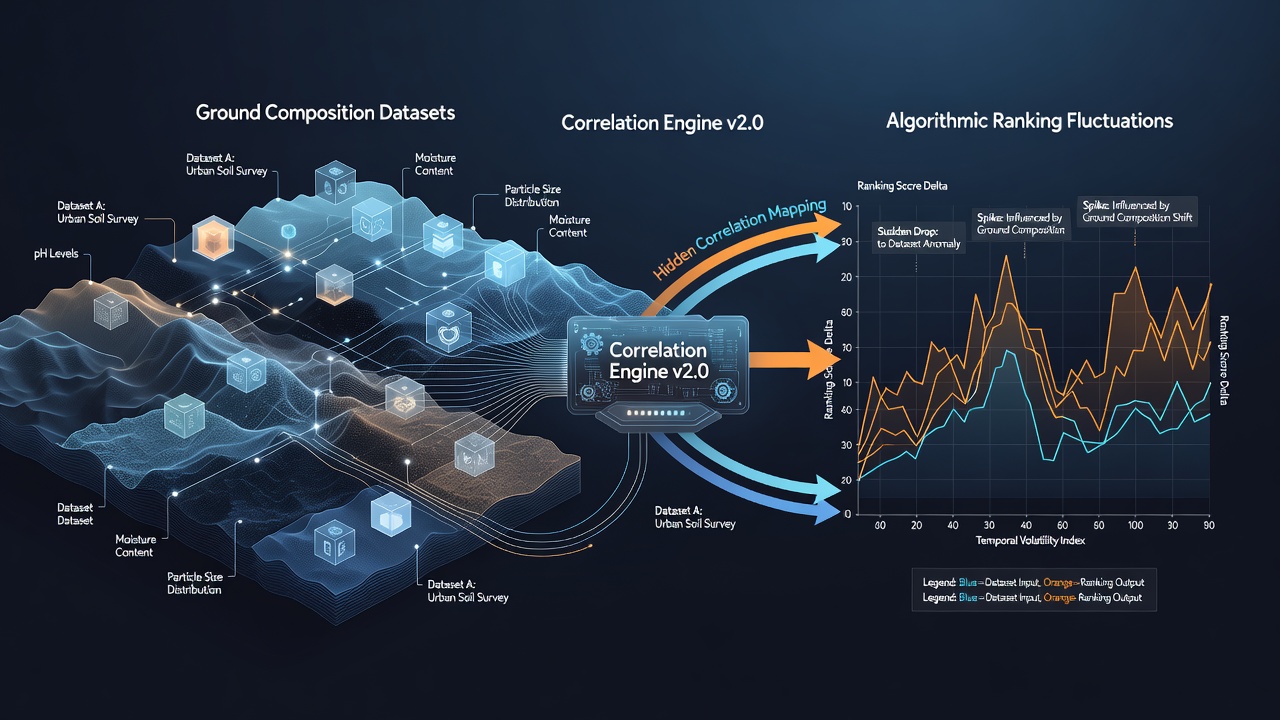
October 2026 brought new releases from several national mapping programs, including refined subsurface models that incorporated higher-resolution moisture readings, and these updates allowed teams to retest earlier correlation hypotheses with improved precision. European Environment Agency records from the same period supplied parallel datasets for cross-regional comparison.
Observed Patterns Across Regions
In zones with high clay content, directory algorithms sometimes elevated listings after heavy rainfall periods because updated location signals reflected temporary changes in accessibility data. Conversely, sandy soil regions showed steadier ranking positions during the same weather events. Researchers cross-referenced these movements against directory API logs and found the timing aligned with when systems ingested fresh geolocation batches. Additional work in Canadian provinces revealed similar alignments when potassium concentration layers were compared against category-specific ranking shifts for agricultural service providers.
Analysts also examined how directory crawl schedules interact with ground data release dates, noting that listings in rapidly updating soil zones experienced more frequent position changes once the new layers entered public repositories. This interaction appears strongest when directories prioritize freshness signals over static business attributes.
Practical Applications for Directory Managers
Directory operators have begun incorporating external geospatial layers during model training to reduce unexplained variance in ranking outputs. By including soil composition as an auxiliary feature, some systems achieve tighter alignment between predicted and observed positions for businesses in variable terrain. Academic papers from Australian research centers describe pilot implementations where such additions lowered fluctuation rates in test directories by measurable margins, though the exact mechanisms remain under further review.
Conclusion
Mapping these correlations requires consistent access to both ground composition updates and ranking histories, along with spatial analysis frameworks that handle multi-source data at scale. As agencies release higher-resolution datasets and directories refine their update protocols, the ability to identify and account for these relationships continues to improve. Ongoing work focuses on refining the temporal offsets between soil data releases and ranking adjustments to support more stable visibility outcomes across regional listings.